Kingdom
Pseudomonadati
Phylum
Pseudomonadota
Class
Gammaproteobacteria
Order
Pseudomonadales
Family
Pseudomonadaceae
Genus
Pseudomonas
Description
Taxonomy
| Kingdom | Pseudomonadati |
|---|---|
| Phylum | Pseudomonadota |
| Class | Gammaproteobacteria |
| Order | Pseudomonadales |
| Family | Pseudomonadaceae |
| Genus | Pseudomonas |
| Species | Pseudomonas sp. SWI36 |
| Strain | No strain |
Profile
| Physiology | |
|---|---|
| Gram staining properties | Not Available |
| Shape | Not Available |
| Mobility | Not Available |
| Flagellar presence | Not Available |
| Number of membranes | Not Available |
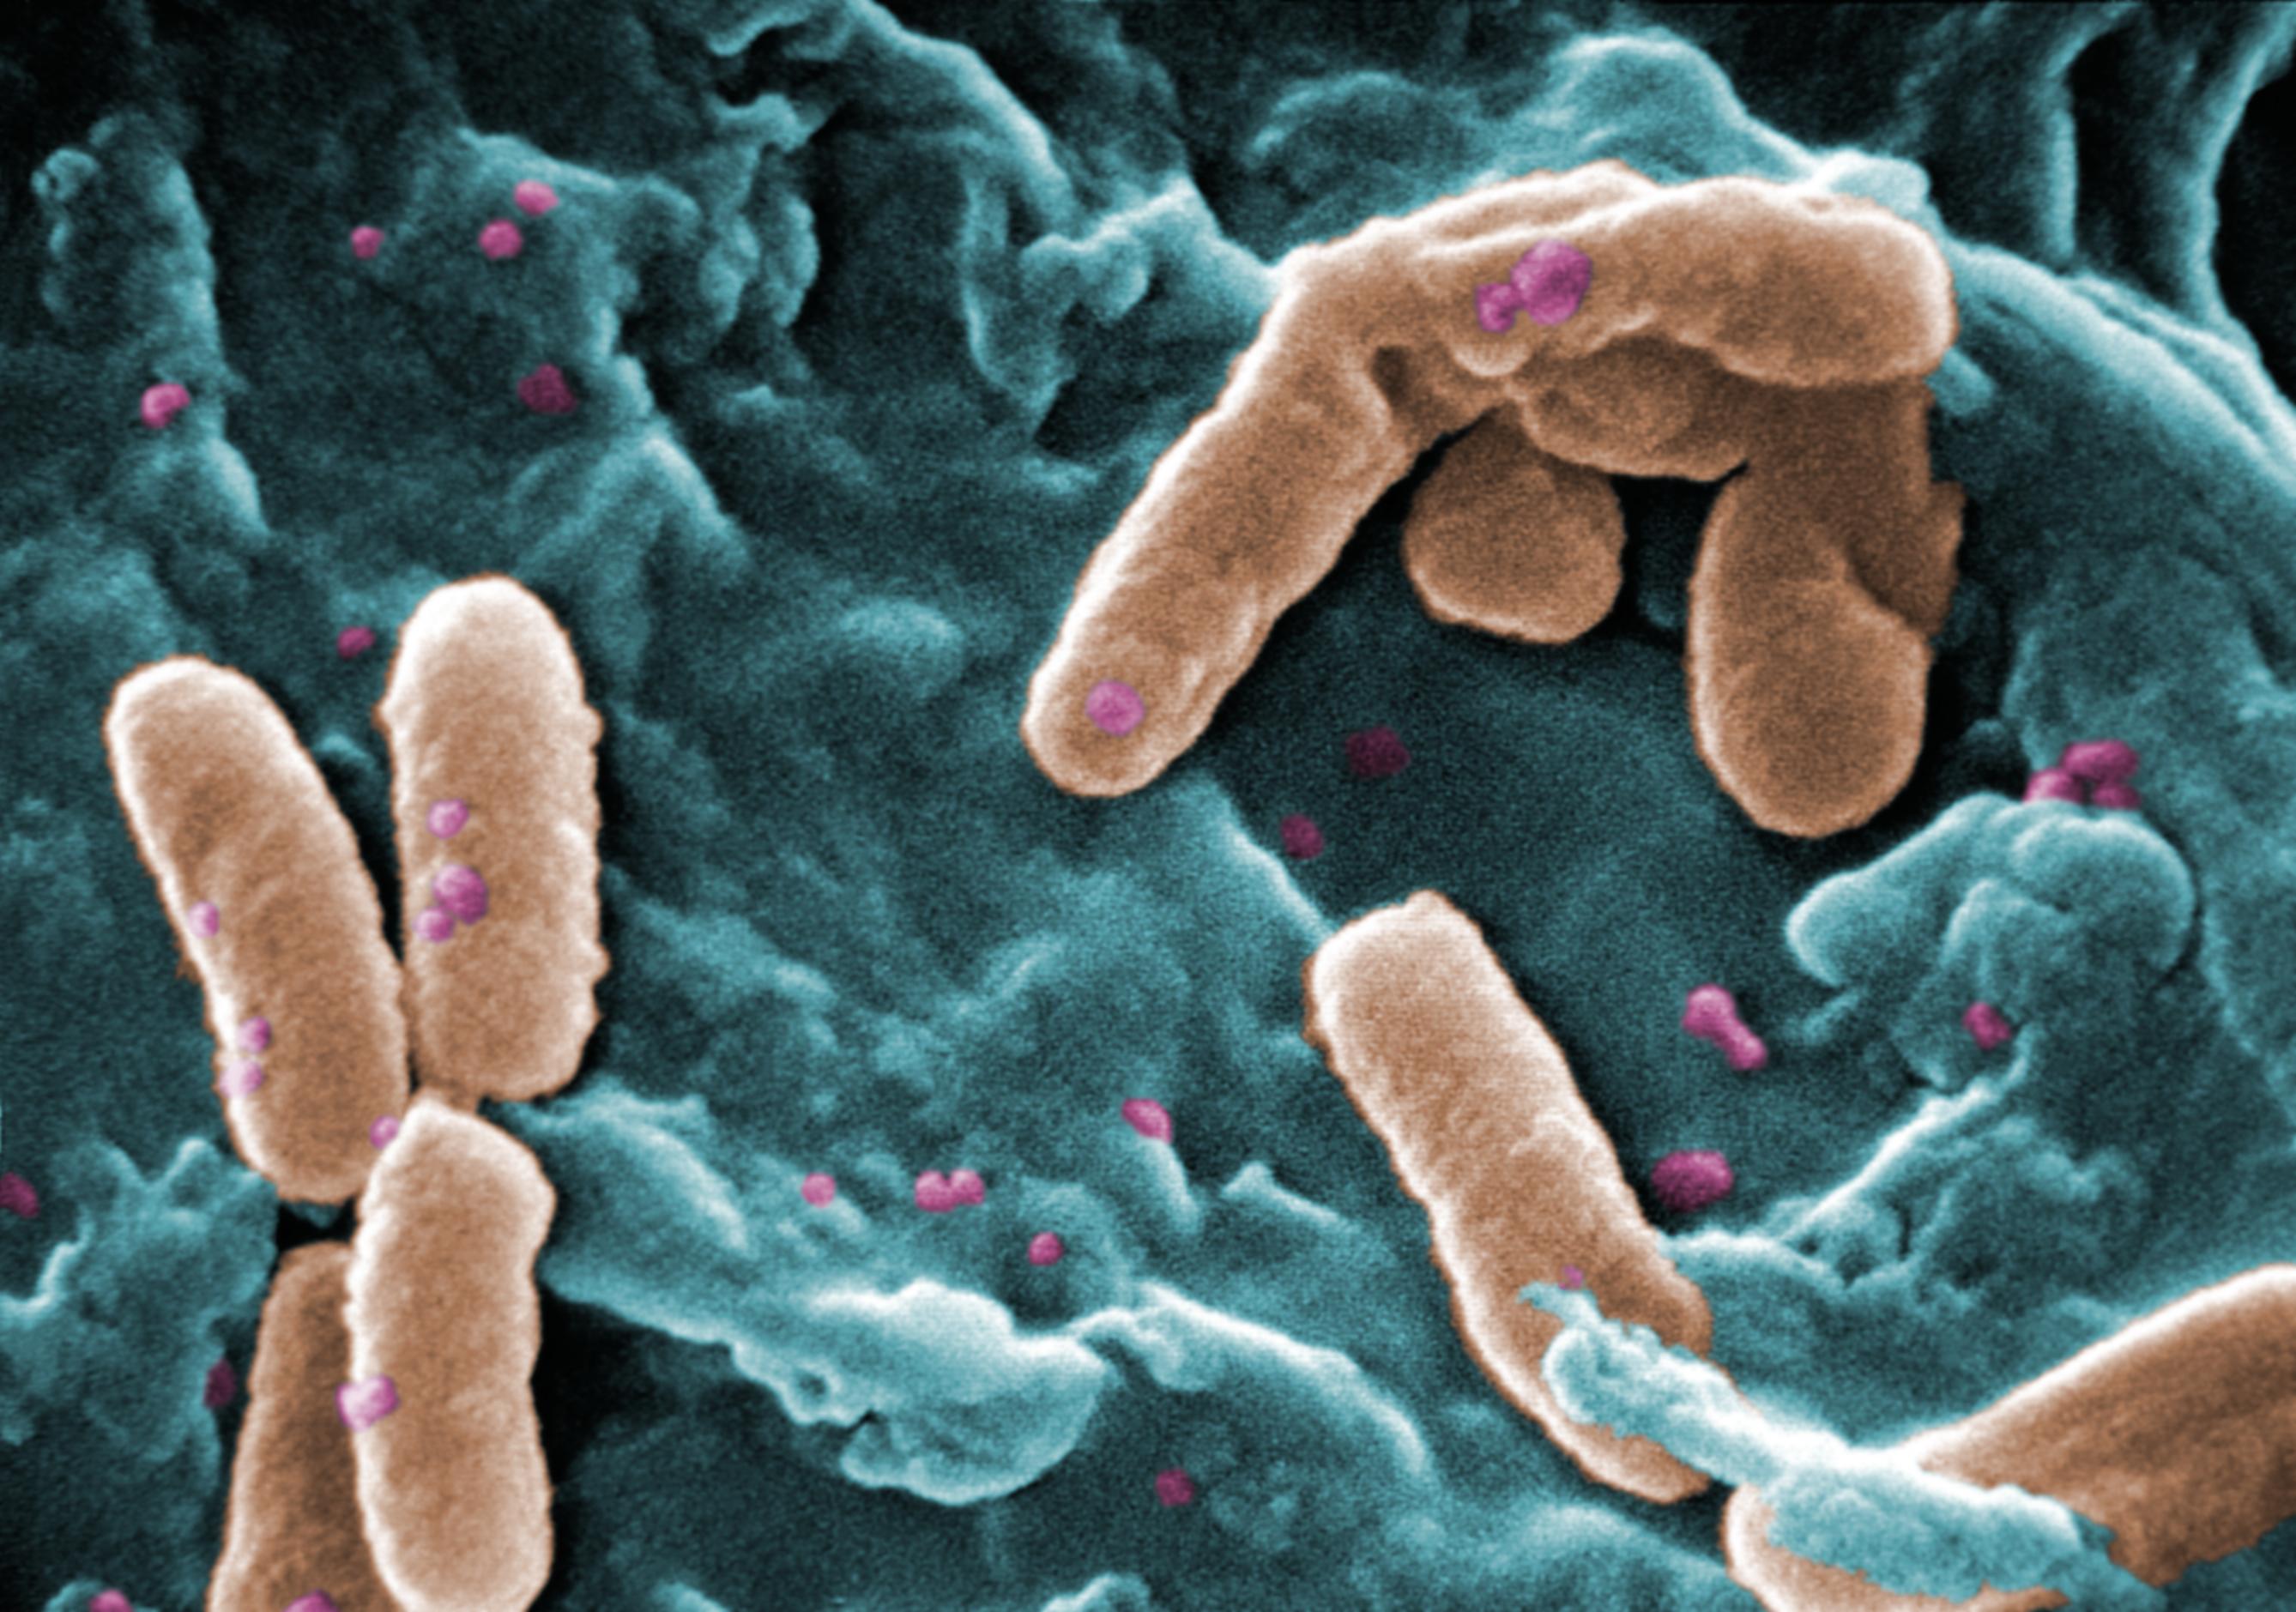
Image source: Wikipedia/Wikimedia
| Ecology, Host, and Life Cycle | |
|---|---|
| Oxygen requirements | Not Available |
| Optimal temperature | Not Available |
| Temperature range | Not Available |
| Habitat | Not Available |
| Biotic relationship | Not Available |
| Host(s) | Not Available |
| Cell arrangement | Not Available |
| Sporulation | Not Available |
| Energy source | Not Available |
| Pathogenicity | Not Available |
Gene Summary
Adenine Count
1175403 bp
Thymine Count
1180188 bp
Guanine Count
1908623 bp
Cytosine Count
1908042 bp
Genome Length
6172256 bp
Protein-coding Genes
5458 genes
Non-Coding Genes
167 genes
# of Chromosomes/Plasmids
1
Genes
| Name | Locus Tag | UniProt ID | Strand Orientation | Gene Start/End | Protein Molecular Weight |
|---|---|---|---|---|---|
| ncs1 family nucleobase:cation symporter-1 | C4Q27_RS03535 | Not Available | Positive | 722543 - 724075 | 55317.5 |
| aspartate/glutamate racemase family protein | C4Q27_RS03540 | Not Available | Positive | 724092 - 724820 | 25800.1 |
| d-amino acid dehydrogenase | C4Q27_RS03545 | Not Available | Negative | 724939 - 726132 | 43357.6 |
| hypothetical protein | C4Q27_RS03550 | Not Available | Negative | 726177 - 726839 | 24304.8 |
| fkbp-type peptidyl-prolyl cis-trans isomerase | C4Q27_RS03555 | Not Available | Negative | 727072 - 727410 | 12166.6 |
| gfa family protein | C4Q27_RS03560 | Not Available | Negative | 727538 - 727945 | 15142.9 |
| phzf family phenazine biosynthesis protein | C4Q27_RS03565 | Not Available | Negative | 728013 - 728801 | 28439.0 |
| 2-hydroxyacid dehydrogenase | C4Q27_RS03570 | Not Available | Negative | 728854 - 729792 | 32909.7 |
| hypothetical protein | C4Q27_RS29270 | Not Available | Negative | 729831 - 730031 | 7248.97 |
| hypothetical protein | C4Q27_RS03580 | Not Available | Negative | 730656 - 731072 | 14943.7 |
Pathways
0 pathways
No pathways found
No metabolic pathways have been associated with this bacterium yet.
Health Effects
No health effects information available for this bacterium.


