Kingdom
Pseudomonadati
Phylum
Pseudomonadota
Class
Gammaproteobacteria
Order
Pseudomonadales
Family
Pseudomonadaceae
Genus
Pseudomonas
Description
Taxonomy
| Kingdom | Pseudomonadati |
|---|---|
| Phylum | Pseudomonadota |
| Class | Gammaproteobacteria |
| Order | Pseudomonadales |
| Family | Pseudomonadaceae |
| Genus | Pseudomonas |
| Species | Pseudomonas sp. SWI36 |
| Strain | No strain |
Profile
| Physiology | |
|---|---|
| Gram staining properties | Not Available |
| Shape | Not Available |
| Mobility | Not Available |
| Flagellar presence | Not Available |
| Number of membranes | Not Available |
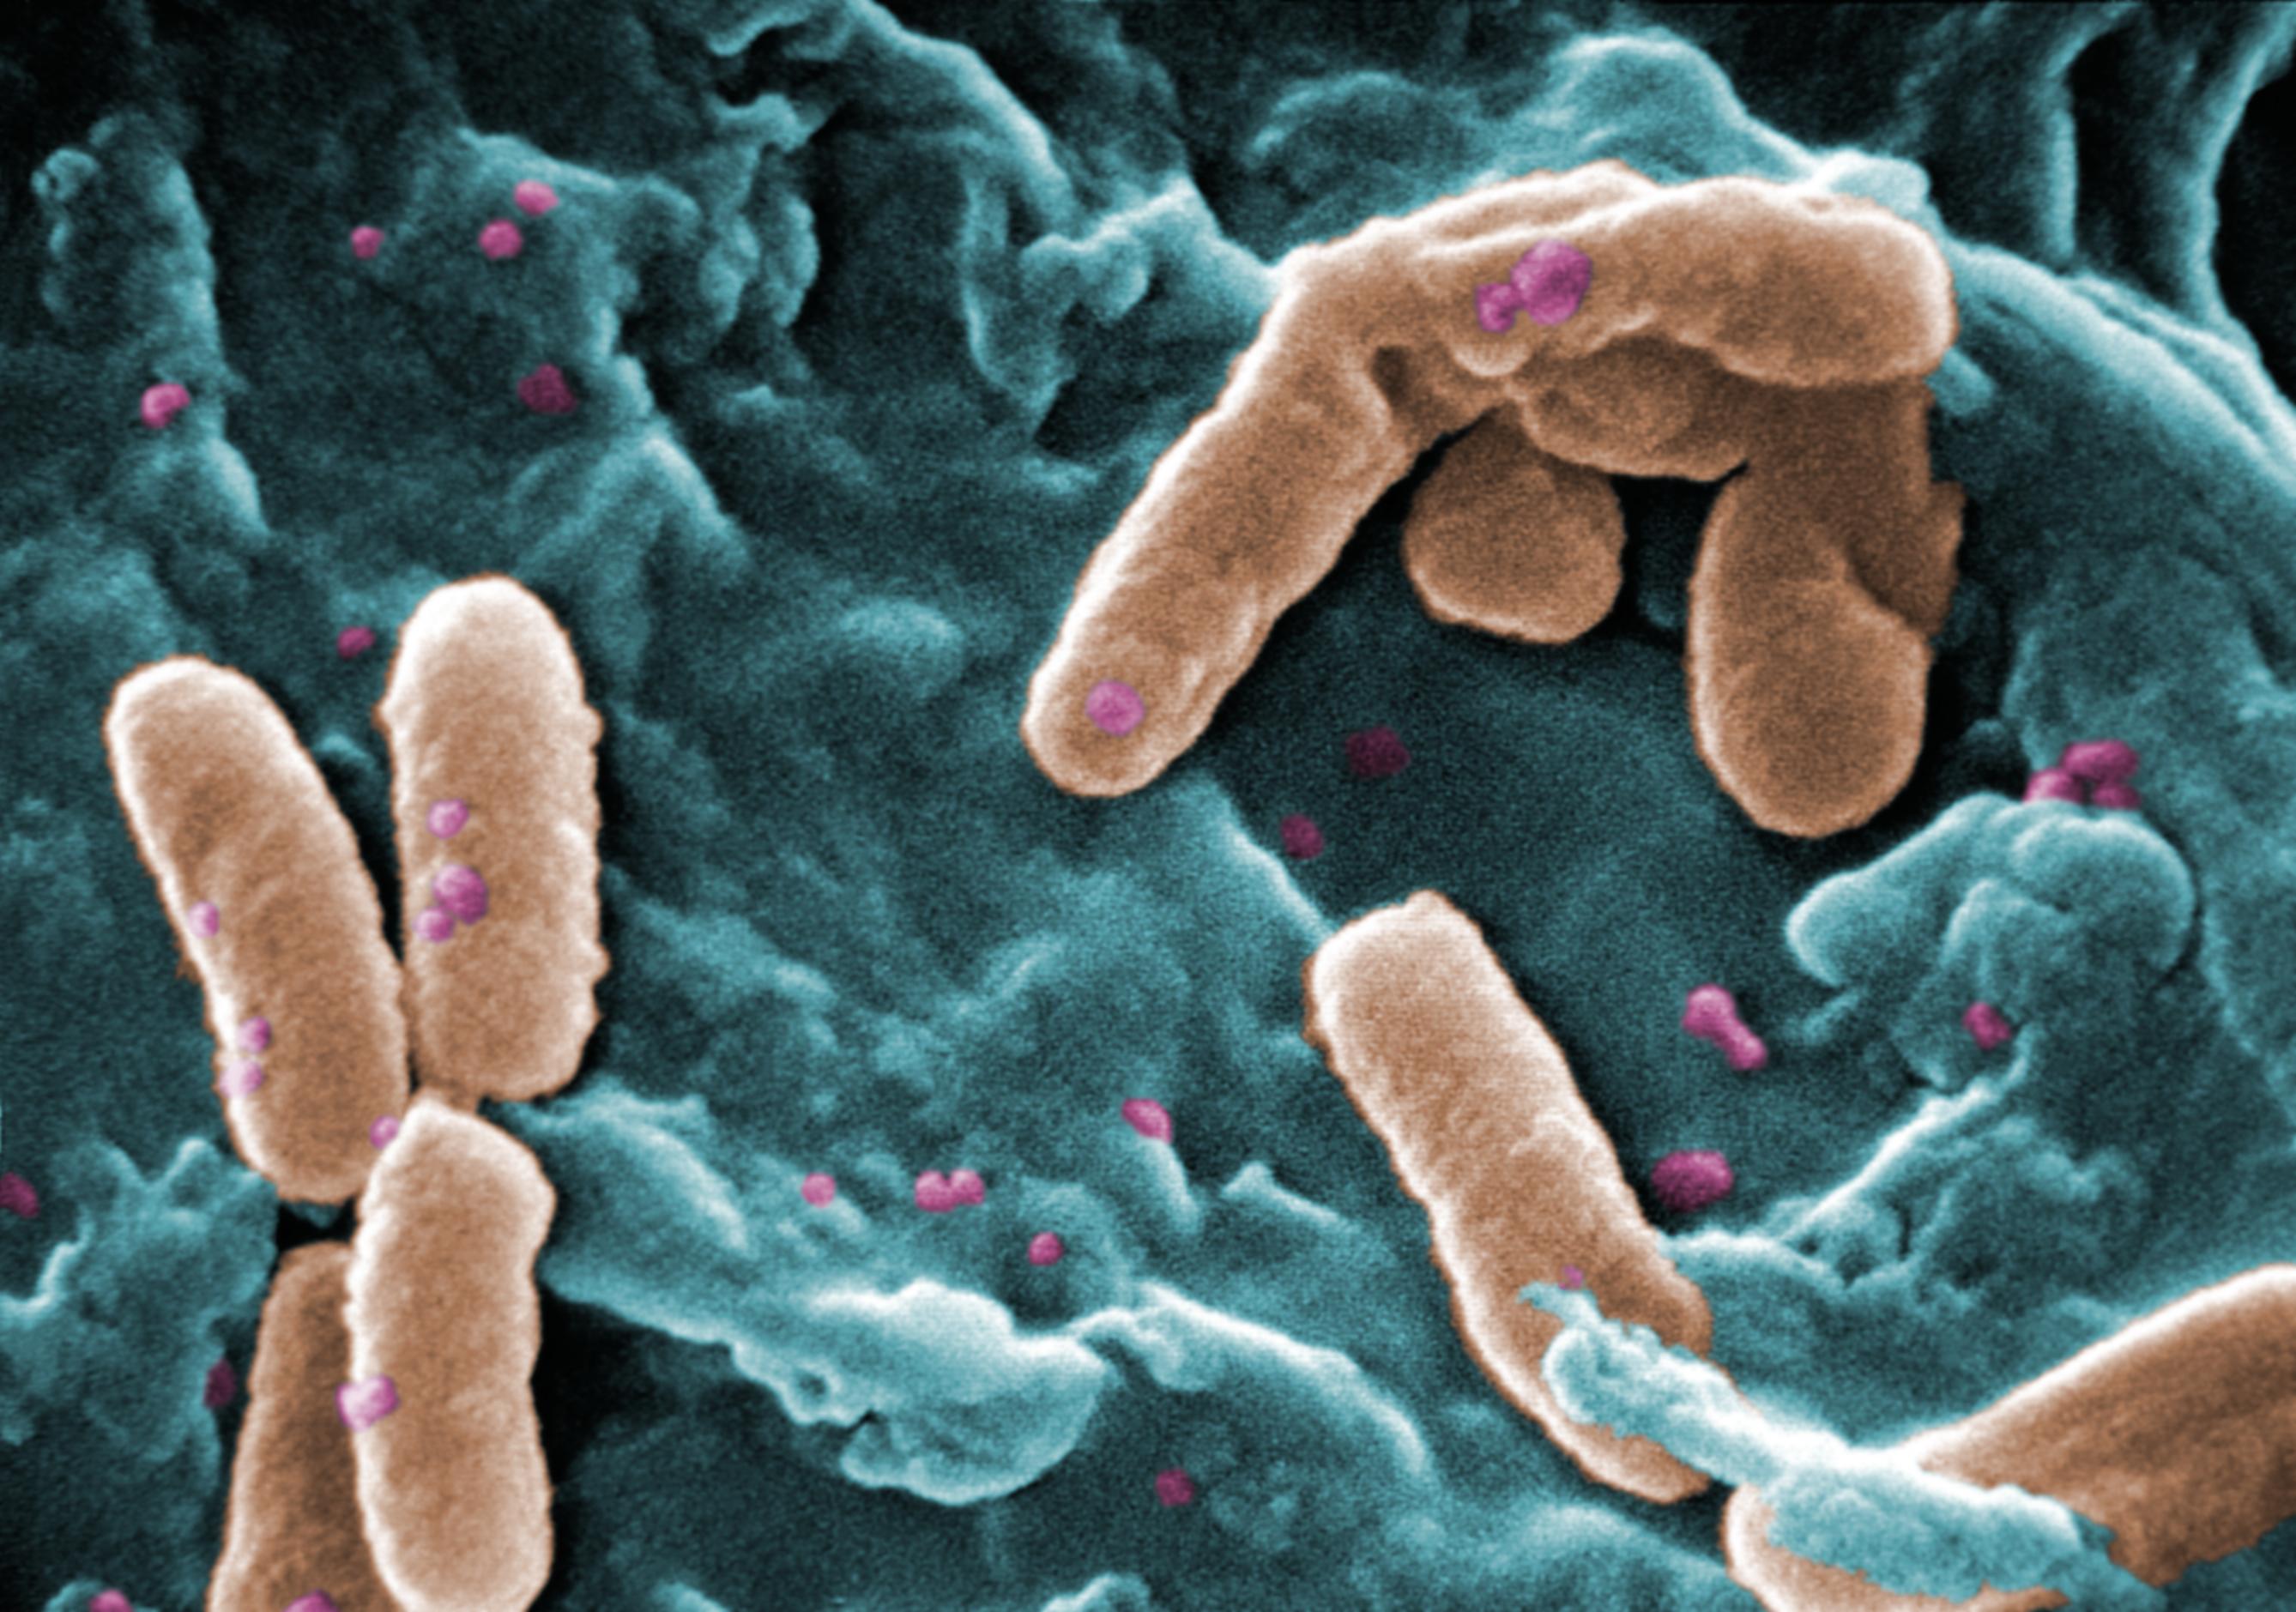
Image source: Wikipedia/Wikimedia
| Ecology, Host, and Life Cycle | |
|---|---|
| Oxygen requirements | Not Available |
| Optimal temperature | Not Available |
| Temperature range | Not Available |
| Habitat | Not Available |
| Biotic relationship | Not Available |
| Host(s) | Not Available |
| Cell arrangement | Not Available |
| Sporulation | Not Available |
| Energy source | Not Available |
| Pathogenicity | Not Available |
Gene Summary
Adenine Count
1175403 bp
Thymine Count
1180188 bp
Guanine Count
1908623 bp
Cytosine Count
1908042 bp
Genome Length
6172256 bp
Protein-coding Genes
5458 genes
Non-Coding Genes
167 genes
# of Chromosomes/Plasmids
1
Genes
| Name | Locus Tag | UniProt ID | Strand Orientation | Gene Start/End | Protein Molecular Weight |
|---|---|---|---|---|---|
| acetoacetate decarboxylase family protein | C4Q27_RS25510 | Not Available | Negative | 5345295 - 5346221 | 33915.3 |
| type 1 glutamine amidotransferase domain-containing protein | C4Q27_RS25515 | Not Available | Negative | 5346336 - 5347139 | 29101.9 |
| nadh:flavin oxidoreductase/nadh oxidase family protein | C4Q27_RS25520 | Not Available | Positive | 5347440 - 5348696 | 45917.4 |
| aaa family atpase | C4Q27_RS25525 | Not Available | Positive | 5348864 - 5349406 | 20954.4 |
| hypothetical protein | C4Q27_RS25530 | Not Available | Negative | 5349469 - 5349927 | 17079.8 |
| lysr family transcriptional regulator | C4Q27_RS25535 | Not Available | Negative | 5350158 - 5351057 | 33486.5 |
| ketopantoate reductase family protein | C4Q27_RS25540 | Not Available | Positive | 5351151 - 5352098 | 32899.7 |
| voc family protein | C4Q27_RS25545 | Not Available | Positive | 5352095 - 5352493 | 14764.8 |
| maoc family dehydratase | C4Q27_RS25550 | Not Available | Positive | 5352490 - 5352945 | 16903.3 |
| caib/baif coa transferase family protein | C4Q27_RS25555 | Not Available | Positive | 5352942 - 5354174 | 44201.8 |
Pathways
0 pathways
No pathways found
No metabolic pathways have been associated with this bacterium yet.
Health Effects
No health effects information available for this bacterium.


