Kingdom
Pseudomonadati
Phylum
Pseudomonadota
Class
Gammaproteobacteria
Order
Pseudomonadales
Family
Pseudomonadaceae
Genus
Pseudomonas
Description
Taxonomy
| Kingdom | Pseudomonadati |
|---|---|
| Phylum | Pseudomonadota |
| Class | Gammaproteobacteria |
| Order | Pseudomonadales |
| Family | Pseudomonadaceae |
| Genus | Pseudomonas |
| Species | Pseudomonas sp. SWI36 |
| Strain | No strain |
Profile
| Physiology | |
|---|---|
| Gram staining properties | Not Available |
| Shape | Not Available |
| Mobility | Not Available |
| Flagellar presence | Not Available |
| Number of membranes | Not Available |
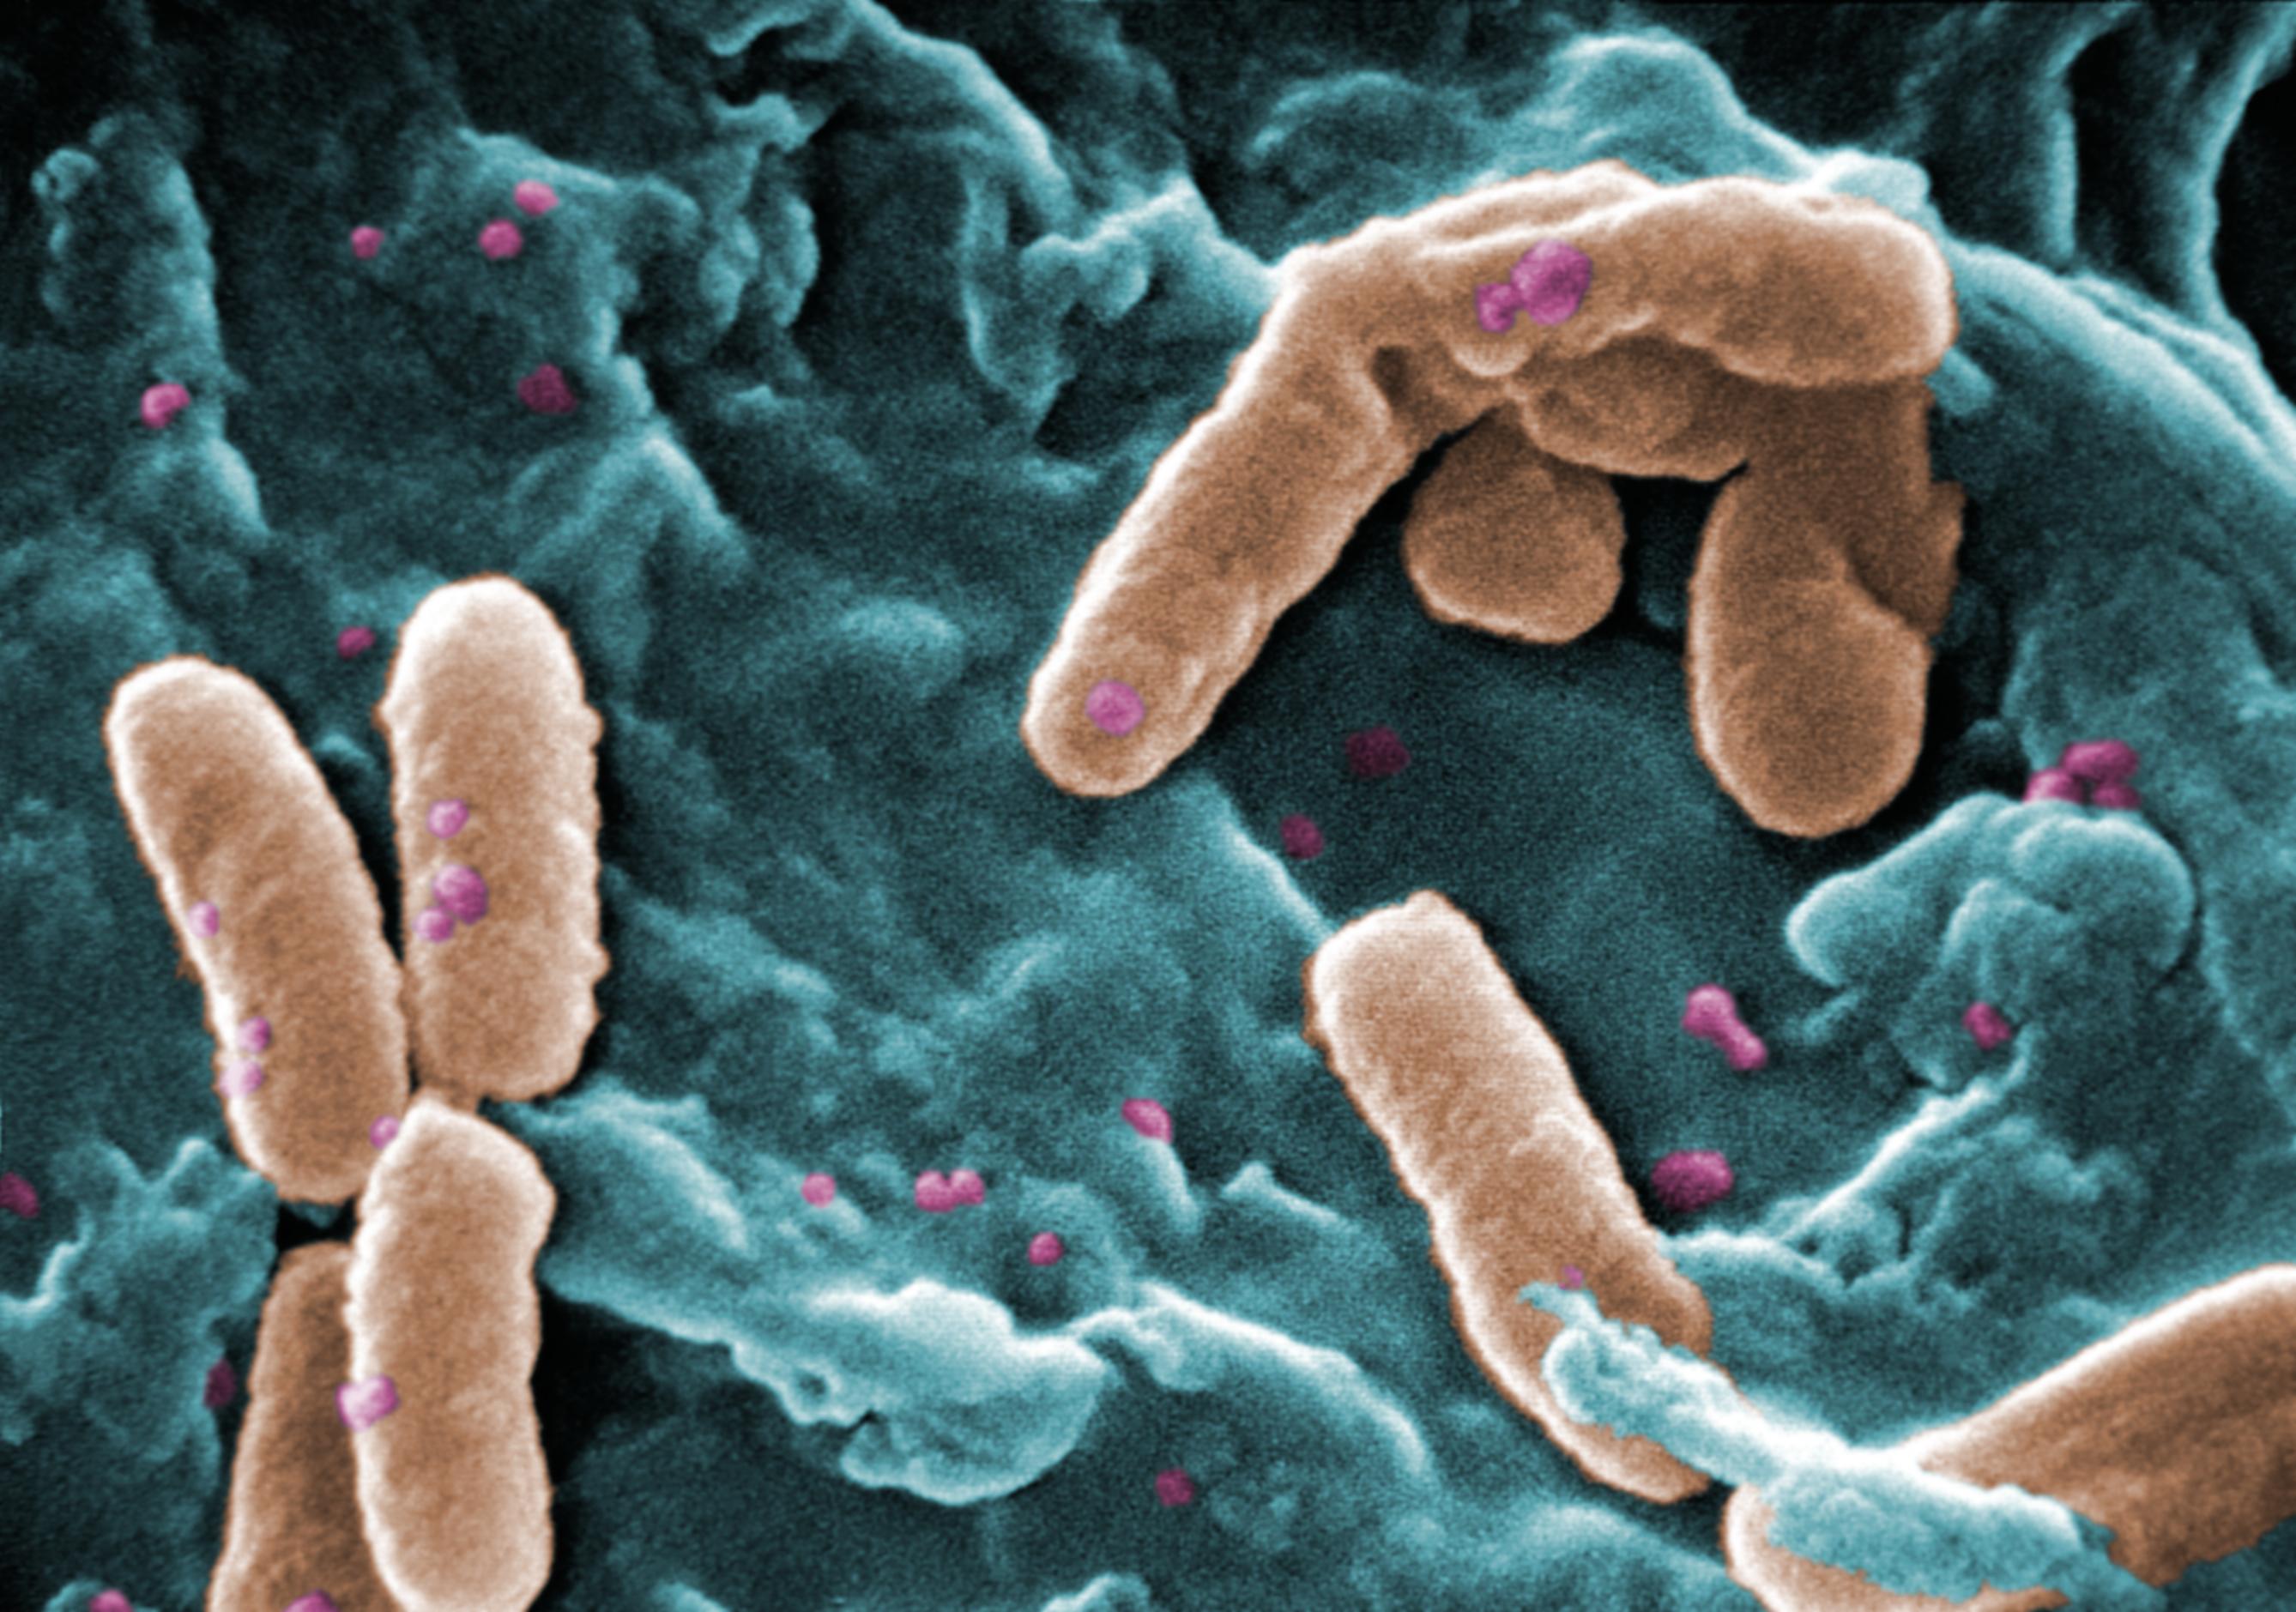
Image source: Wikipedia/Wikimedia
| Ecology, Host, and Life Cycle | |
|---|---|
| Oxygen requirements | Not Available |
| Optimal temperature | Not Available |
| Temperature range | Not Available |
| Habitat | Not Available |
| Biotic relationship | Not Available |
| Host(s) | Not Available |
| Cell arrangement | Not Available |
| Sporulation | Not Available |
| Energy source | Not Available |
| Pathogenicity | Not Available |
Gene Summary
Adenine Count
1175403 bp
Thymine Count
1180188 bp
Guanine Count
1908623 bp
Cytosine Count
1908042 bp
Genome Length
6172256 bp
Protein-coding Genes
5458 genes
Non-Coding Genes
167 genes
# of Chromosomes/Plasmids
1
Genes
| Name | Locus Tag | UniProt ID | Strand Orientation | Gene Start/End | Protein Molecular Weight |
|---|---|---|---|---|---|
| arginine decarboxylase | C4Q27_RS08595 | Not Available | Negative | 1758531 - 1760444 | 71047.4 |
| translation initiation factor sui1 | C4Q27_RS08600 | Not Available | Negative | 1760595 - 1760966 | 12821.5 |
| nudix hydrolase | C4Q27_RS08605 | Not Available | Negative | 1761206 - 1761739 | 19665.2 |
| duf2333 family protein | C4Q27_RS08610 | Not Available | Negative | 1761742 - 1762809 | 39405.8 |
| diguanylate cyclase | C4Q27_RS08615 | Not Available | Positive | 1763057 - 1764412 | 50304.8 |
| methyl-accepting chemotaxis protein | C4Q27_RS08620 | Not Available | Positive | 1765064 - 1766617 | 55168.5 |
| protein-disulfide reductase dsbd | C4Q27_RS08630 | Not Available | Positive | 1766806 - 1768578 | 62514.1 |
| type ii 3-dehydroquinate dehydratase | C4Q27_RS08635 | Not Available | Positive | 1768758 - 1769213 | 16491.8 |
| acetyl-coa carboxylase biotin carboxyl carrier protein | C4Q27_RS08640 | Not Available | Positive | 1769313 - 1769774 | 16186.6 |
| acetyl-coa carboxylase biotin carboxylase subunit | C4Q27_RS08645 | Not Available | Positive | 1769792 - 1771147 | 49091.0 |
Pathways
0 pathways
No pathways found
No metabolic pathways have been associated with this bacterium yet.
Health Effects
No health effects information available for this bacterium.


